The hard problem isn't verification. It's preparation.
An attorney examining a witness has access to thousands of pages of discovery—contracts, emails, prior testimony. Reviewing those documents against live testimony is work that takes a paralegal days. An LLM querying a vector store of those same documents takes seconds.
The obvious architecture is straightforward: transcribe the speech, send it to a language model backed by a document store, return the results. This approach is fast. It is also, in many cases, meaningless.
A witness says "yes." The system receives the word "yes" with no context for what was affirmed, no question to anchor it, nothing to verify. A witness says "she hit him with it over there." Every content word except the verb is an unresolved reference. The model returns a confident, well-structured answer either way.
A pipeline of small, auditable steps.
Vega processes audio through a sequence of stages, each of which transforms the output of the prior one. None of the stages is clever on its own. Together they turn dialogue into propositions worth checking.
- /01ingestLive stream or uploaded file is normalized into sentence-level utterances with speaker tags.
- /02clean & classifyEach utterance is cleaned of ASR artifacts and labeled question, assertion, or other. The two run in parallel.
- /03bundleUtterances are aggregated into question-and-answer pairs—the smallest unit of dialogue with enough context to verify.
- /04resolve entities"He," "the company," "my client" are disambiguated against a session context that tracks participants and aliases.
- /05discernProcedural exchanges and off-topic asides are explicitly marked as not worth analyzing—visibly, not silently.
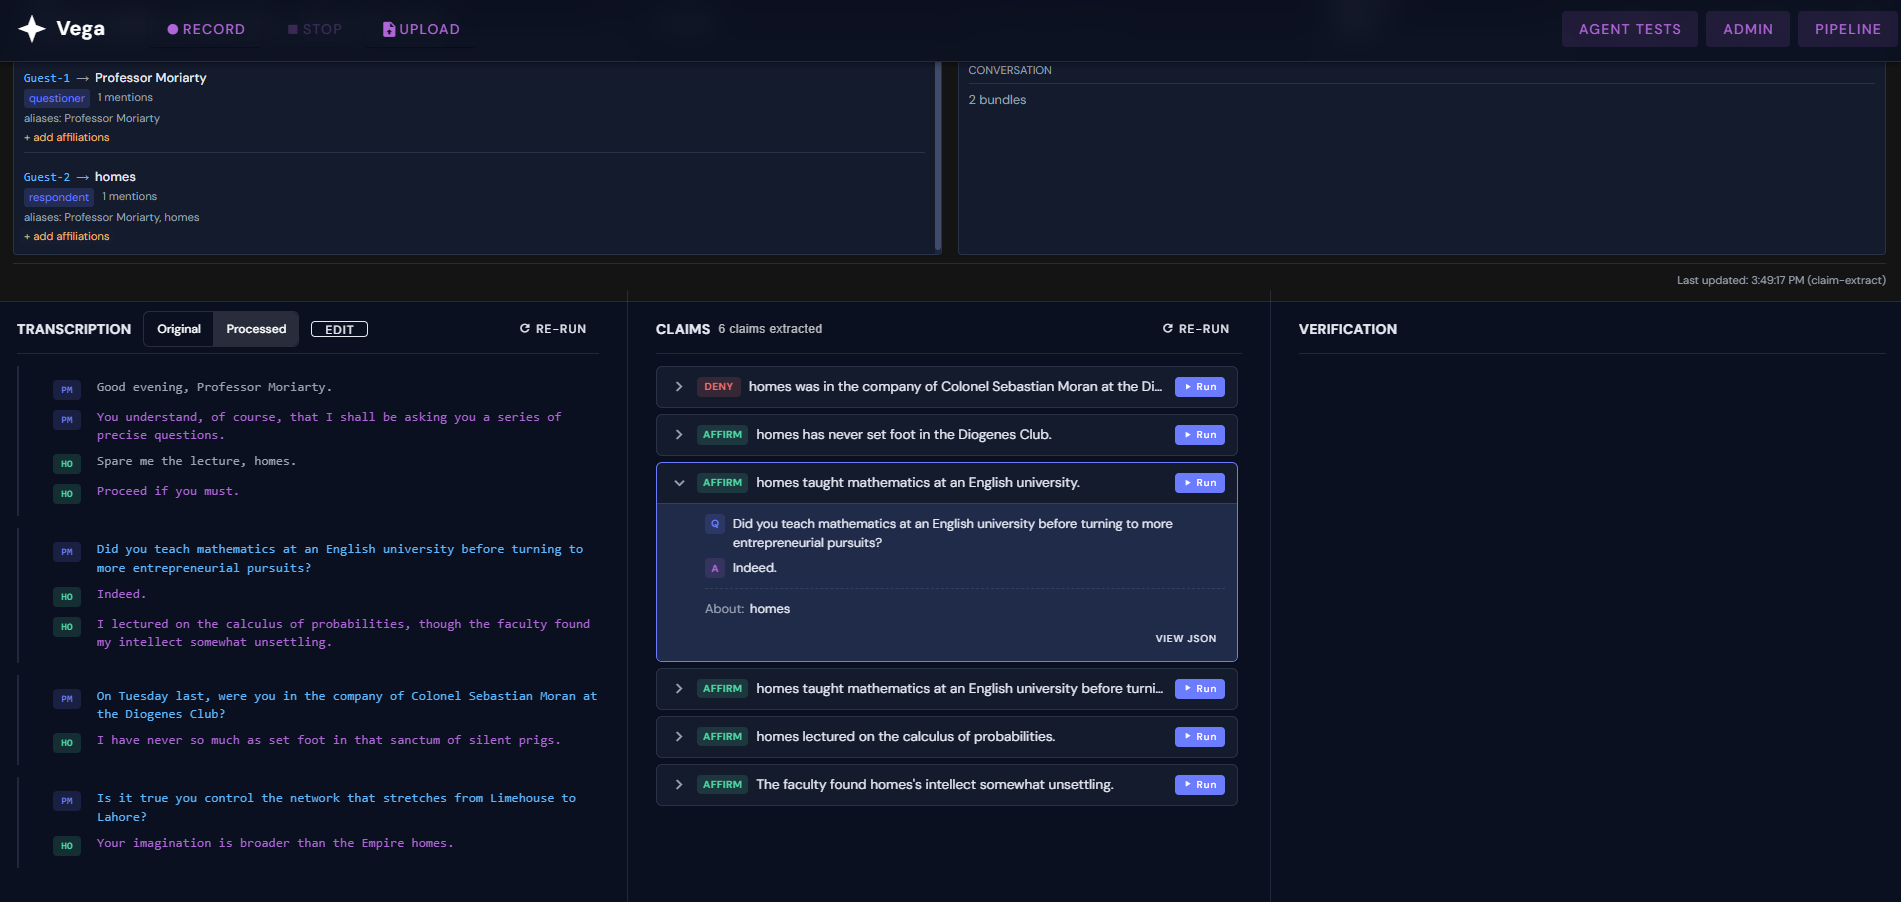
- /06quality cleanWith session context now available, "the empire homes" becomes "the empire, Holmes."
- /07extract claimsEach enriched bundle is decomposed into discrete subject-predicate-object propositions.
- /08verifyClaims are evaluated against the document corpus—supported, contradicted, mixed, or unverifiable—each with reasoning and citations to the source passage.
Testimony doesn't wait for the pipeline: new utterances arrive while earlier bundles are still mid-stage, so every stage has to know what it can safely act on. Concurrency is handled by a Harel statechart (XState): each utterance and each bundle has its own state, with guard conditions enforcing the dependency chain. A flat finite state machine collapses; five bundles in six states is 7,776 combinations.
Six rules that survived the build.
The paper extracts six design principles from the implementation—portable beyond Vega and beyond legal AI—and pairs each with a counterexample where the system falls short. The short versions:
- / p1
Separate inference from control.
Model calls are bounded jobs with defined inputs and outputs. Sequencing, retries, and state transitions live in a deterministic orchestrator that never needs to know which model ran.
- / p2
Prefer replayability over determinism claims.
LLM stages vary between runs; claiming otherwise is dishonest. Every AI-mediated stage records its input, output, model, and prompt version, so any result can be inspected and re-run.
- / p3
Treat human correction as state, not annotation.
An analyst correcting a speaker assignment isn't leaving a note. The correction updates the state downstream stages read, and automated reruns preserve it.
- / p4
Layer deduplication, then state its limits.
Duplicates enter at ingestion, event handling, stage triggers, and assembly. Guard each layer, and document what each does and doesn't guarantee, rather than claiming global idempotency.
- / p5
Keep stage contracts stable, providers replaceable.
Each stage has a fixed input and output shape; the model, prompt, and settings behind it are configuration. A better model is a one-stage change.
- / p6
Expose selective adjudication.
Analysts can re-run one stage or re-verify one claim without reprocessing the session. One flawed result shouldn't cost everything around it.
The argument isn't that Vega is the right answer. The argument is that any system attempting to make real-time legal AI trustworthy will encounter these problems—and the path from fast to trustworthy is a systems design problem, not a model selection problem.
- paper
- Matteson, R. (2026). One Shot: Architecture Principles for Trustworthy Legal AI.
- ssrn.com/abstract=6475999
- built
- 2023–2026
- author
- Robert Matteson
- Product design, interface, system architecture
- stack
- Microsoft Speech SDK · multi-model orchestration · XState · vector retrieval
- status
- Independent research project. Documented; not in service.